Wednesday, June 11, 2014

Coming soon: DBDOC 10.5.1, with NEW error sharing and improved SPlus/PGP and PG2 support

We're now in the home stretch for getting the next DBDOC release out the door.  DBDOC 10.5.1 includes major expansion of some of the new features introduced in DBDOC 10.5, as well as general bug fixes and feature improvements

There is good news for users of SPlus/PGP graphics.  As we receive feedback and gain experience from client systems using DBDOC 10.5,  support continues to be solidified, especially for systems converted from PPB and Conductor NT.

In addition, there is a whole new approach to 800xA graphics.  Using tools created for DBDOC by  ASSYST (included with your DBDOC installation) it's easy to extract more comprehensive PG2 or VB data for better integration of 800xA graphics into the DBDOC snapshot.

The other major new feature for DBDOC 10.5.1 is the introduction of error sharing.  Really this is just the first step along the road of allowing Hyperview users to share data in general.  Right now, each Hyperview user is relatively isolated, making independent annotation notes on projects, bookmarking significant items, creating and configuring Watch Window groups, and, as of DBDOC 10.5, managing and reviewing system errors in the new Error Browser.  The vision, however, is for all these activities to become more collaborative.  A whole group could take advantage of a predefined set of bookmarks, or view notes made by others.  It takes time to set up Watch Window groups, configured appropriately for monitoring particular situations.  Ideally these groups (and the data collected in them) could be easily shared among multiple users if desired.

So this is the direction Hyperview is heading, and the first example of this sort of sharing actually implemented is the sharing of error information, i.e. the stars and checks added to errors displayed in the Error Browser.

User data is shared via a shared folder accessible to multiple Hyperview users.  Usually this folder will be specified in BuildPlus, when a project is built, and will show up automatically in Hyperview.  To start sharing data with other users, all you need to do is "register" in this shared data folder.  Go to the Options menu in Hyperview, choose the Sharing tab, and (if a shared data folder has been built into your M14), just hit Apply and you're done.  If not, you can manually choose a data sharing folder.


When you open the Error Browser in 10.5.1, you will notice a new list on the left, listing all the users that have registered to share their error information.

 
By checking and the boxes next to the names of other users, you can cause their stars and checks to be displayed in your Error Browser.   By setting various filtering options, you have control over which errors you display.  For example, you could display only the errors starred or reviewed by a particular user.  Once the errors are displayed, you could select them all (for example) and hide them, or mark them as reviewed yourself.
 
This functionality is simple but powerful, because for the first time, it really makes it easy and convenient for groups of users to collaboratively review and manage errors.  A typical system will have hundreds of build errors, many of which are not serious in context, but all of which should be reviewed for safety.  The ability to split up and coordinate this error review process is extremely useful, and was requested by a number of early Error Browser users.
 
DBDOC 10.5.1 will be released and available within the next few weeks.  For an early look at the new features still under test, you can download DBDOC 10.5.1 Beta from the GMCL website.


Tuesday, June 3, 2014

DBDOC Visits the Peak District


Geoff and I are visiting clients in England for the next two weeks. On Monday we visited our first client, a cement works (Hope Works) in the Hope Valley, Derbyshire, a very pretty place. The villages are beautiful, set among large hills and occasional rock outcroppings rather than mountains. Of course, there are sheep everywhere. The weather was warm, approaching 28 degrees C with blue skies and sunshine as we started work in the morning.


The stone house is the B&B where we spent Sunday night. At several hundred years old it is an historic site, as the oldest of many similar ones are in the village. The ceilings are supported crosswise with large thick oak beams. In all very charming for our first night in England.

The sunshine, however, was not to last. By afternoon clouds had come up, and as we drove away in the late afternoon the rain started. Fog blurred the landscape and a picture of the rock outcroppings was not possible. The rain followed us to our next stopping place, Happy Guest Lodge at Warrington, Cheshire. Here we are today, with a day off, until we start visiting with clients for the rest of the week. Next week we will be visiting clients in the London area.

Thursday, May 1, 2014

Keeping XP secure as Microsoft's support slowly ceases

Today, Microsoft released a patch fixing a potentially serious (although some at Microsoft have called it "overblown") security bug that allowed for remote code execution through Internet Explorer 6 through 11. In their initial advisory for the issue, they listed affected Windows versions without mentioning XP. With this patch, they've apparently decided that it's important to patch XP too for this one. But rather than cause for celebration for XP users, this should be one last wake-up call; coming mere weeks after XP was dropped from support, Microsoft decided to patch through this time, but they're making no promises that there'll be a next time.

Here at GMCL, most of our physical XP machines have been retired, and we do most of our testing for it in hardware-accelerated virtual machines (which combines running a 'real' install with the ability to quickly snapshot and revert as desired). But a few machines still linger for one reason or another, so how do we approach maintaining them? Well, here's a few thoughts on the subject that I've arrived at, which I think apply generally:

  • Don't delay on upgrading: Obvious, but deserves stating first. Practical realities may make it seem too difficult, and one might imagine oneself to be secure, but even if XP was very amenable to being secured (and, in many folks' opions including mine, it really isn't), it's going to be an increasingly huge target. And even if you have an air gap in theory, in practice air gaps are nearly impossible to fully maintain; as Paul Ferguson of Trend Micro wrote in his white paper "Toward a More Secure Posture for Industrial Control System Networks", in "practical and operational terms...physically separating networks is not functionally nor operationally feasible in the real world." So for any systems still running XP, it should not be if you upgrade or replace them, but when.

  • Drop IE for Chrome or Firefox, wherever and whenever possible: Microsoft's policy for Internet Explorer updates is to tie them to support for the OS version in question, so while Internet Explorer versions for Server 2003 and 2003 R2 will continue to get updates until 2015-07-13, those that shipped with XP aren't officially guaranteed to recieve any more updates after April 8th---as Microsoft representatives have explicitly stated, today's update is "an exception". But Google's Chrome browser and the Mozilla Foundation's Firefox both will support Windows XP, and thus provide security updates on it, past the April 8th drop-dead date. Google is intending to update Chrome for Windows XP until at least April 2015, and Mozilla currently has no plans to discontinue support. Both browsers have proven in the past to be more secure out-of-the-box than Internet Explorer, and although contemporary versions of IE have significantly improved in this area (and many others), those versions won't run on XP anyways.

    You may well have internal sites or systems that rely on the older IE versions (especially if they involve ActiveX controls), but considering the web browser is perhaps the primary vector of infection, it is worth seriously evaluating the possibility of migration, and at very least using IE only in the specific instances you need to. In fact, for Google Chrome there is an official extension that can be installed on managed Chrome installations which allows you to specify automatic switching between IE and Chrome based on listed sites, thus allowing you to cordon off only specific internal sites to be browsed with IE.

  • Enabling Internet Explorer's Enhanced Security Configuration: To the degree that ditching Internet Explorer isn't an option (or that you truly prefer it as a browser), there's always the Enhanced Security Configuration. This is enabled by default on all versions of Windows Server, and can be enabled (piece by piece) on Windows XP. It beefs up security at the expense of some convenience--in fact, we've even run into some small bugs with the DBDOC Error Browser when ESC is enabled (relating to copy/paste). In this case, especially when XP is concerned, the convenience traded off seems potentially worth the added security, but that is indeed the classic dilemma.

  • Using the Enhanced Mitigation Experience Toolkit: Microsoft's EMET is a tool that hardens applications by preventing the kinds of behaviours and faults that are often exploited by malware. As such, it's quite useful for preventing unknown or unpatched vulnerabilities from being exploited. It's enabled per-application, so you can be granular and choosy with this one.

  • Uninstall anything you don't use: The converse of using the EMET to harden applications is to make sure any you don't actually need aren't there to be exploited. Alongside the news of the recent IE exploit, there's also an Adobe Flash exploit recently discovered in the wild. Many XP machines may have components like Flash and Java installed that they don't actually need for daily operations, and the machines in question will be safer without the additional attack surfaces lying in eager wait.

  • For anyone out there, what are your thoughts? Are you already working to upgrade? Is it out of your hands? Do you have any other suggestions for keeping XP as secure as possible as it sails well past its best-before date?

    Thursday, March 13, 2014

    Try DBDOC on a Tablet: It Just Works!

    Recently we brought a Surface Pro tablet into our office, and we've been pleasantly discovering that for the most part, DBDOC Just Works! Read on for more details.
     
     
    Lets look at Hyperview, which is the most likely of the DBDOC programs to be used with a tablet.

    First up, we have an option in Hyperview that happens to have prepared us for touchscreens entirely unintentionally. If you go into "Options..." you'll see in View the checkbox for "Large icon toolbar", which scales up the main buttons.


    Who knew we were preparing for touchscreens all this time? It's nice to be forward-thinking by accident!

    Most navigation works as you'd expect. Tap on the screen for left-click; long-press for a right-click, for example to call up a context menu on a block; scroll by flicking within a pane or by pressing down on a scrollbar and moving your finger. It can be a bit inconsistent sometimes, and we're investigating an issue where kinetic scrolling in the index pane stops working on some M14s, but in general it's quite fine with fingers or a stylus.

    Selecting an area to zoom into can be a bit tricky with the touchscreen, although I've found it to be fairly reliable if I start first with a distinctly horizontal motion, then start moving my finger vertically as well. Otherwise, Windows sometimes interprets the motion as an attempt to drag the viewspace. With the stylus that comes with the Surface Pro, however, box selection seems to work without hassle.

    If you're running Windows 8.1 on a relatively high-DPI device like the Surface Pro or a new high-end laptop, you may notice the fonts are a bit blurry. This is because Windows 8.1 by default scales up the UI element sizes when using a dense display, which is handy for keeping things readable (and for making it easier to touch interactive elements), but isn't done in a way that's terribly kind to applications built on the old standard Windows assumption of 96dpi. Right now, most third-party applications for Windows react in one of two ways: either upscaling with blurry fonts and other elements, or ignoring the scaling entirely. You can see this contrast with the current versions of Google Chrome and Mozilla Firefox for Windows, where the former looks the same as DBDOC does and the latter stays crisp but small in defiance of Windows' scaling settings.

    If you haven't noticed this (in which case, sorry for pointing it out!) you can leave it as-is, but if you're looking to disable scaling globally, you can find the option in "Control Panel\Appearance and Personalization\Display". You can also disable in on a per-application basis by right-clicking on a shortcut or an EXE, going into its properties, and choosing "Disable display scaling on high DPI settings" from the Compatibility tab.


    We're investigating and evaluating how we might hook DBDOC into the scaling functions of contemporary Windows, which will not only help with tablets like the Surface Pro, but also high-resolution desktop and laptop displays which are just now starting to edge into mainstream production; my own laptop has a resolution of 2560x1700 on a mere 13" screen!

    Well, that's the rote details of the current state of running Hyperview on Windows 8/8.1 tablet, but what's the actual use? Well, we've imagined that it could be quite helpful carrying around a plant, looking at live data (if you're connecting in through a local network or VPN) or even just to be able to easily browse your graphics and CAD sheets while standing in front of the actual machinery they represent. You could use CIUMon Relay to pass on data from a running CIUMon instance, or even hook up a USB-to-serial adapter to your tablet and plug in directly to a CIU with your tablet. And the guts of Microsoft's Surface Pro and Surface Pro 2 are fairly hefty, so you could even run BuildPlus to generate M14s if need be.

    We're just getting started on touchscreen and tablet support, so let us know what you would find useful and in what scenarios you can see using DBDOC on a tablet!

    Monday, January 13, 2014

    Are Dated Design Compromises Affecting Your HMI and History Data Precision?

    I got busy in the purported Christmas break and wrote a bunch of blogs.  This blog is a roadmap through several related areas. Read on to
    • learn if you are overloading the exception report generation of nodes
    • verify under-utilization and improve your console and history data
    • automatically detect and report exception report delays
    Most systems worry about the above, and most were configured a decade or two ago. Learn if you can get much more out of what you have.

    For many INFI 90 systems, the power of the modern NIS21/NPM22 hardware capability will allow you to get much more precise data to consoles and history systems.

    If you have DBDOC, you can find out, for every PCU / node that you think is heavily loaded, if it really is. Heavy loading is 50% to 90%, overloading above that.  This is how to do it:

    Monitoring Node Communication CPU Load

    If you find the communication CPU usage in the 10% range, you are not getting enough out of INFI 90 and are not giving operators, managers and engineers data that is good enough.  You can do better:

    Improved Tag and History Data Precision in INFI 90 Systems

    There is also a design for you to be able to permanently and validly measure whether you ever get delayed or lost exception reports.  If you find you have nodes in the 50% or greater node communication CPU usage, you should worry about this.

    Monitoring Exception Report Performance

    Have you tried any of these techniques?  It would be very interesting to hear your experiences.

    Friday, December 20, 2013

    The Art of DBDOC - Live Specs and NVRAM Failure

    Summary

    NVRAM failure can be a big problem.  Doing a DBDOC Live Loop Annotation fetching the block specifications will fail if the NVRAM has failed.  This could be useful information to you.

    Details

    A client reported that DBDOC Hyperview could not fetch the specs of a block.  In fact, the specs could not be fetched in any block in that module.  This is shown in this image.  Live data could be fetched - only the reporting of the specifications was affected.


    However, fetching specs worked fine in other modules.  The example in a clone of the problem one, as you can see.


    What could cause this problem? 

    The next two images show the difference between working and failing module status fetches. 


    Guess what?  The problem module shows NVRAM failure status: Fail.  The one that is working says: Good.

    From the Client

    "I believe a NVRAM failure will prevent looking at any of the configuration."

    Subsequent Perspective

    "The module will continue to operate with an NVRAM error because a copy of the configuration is held in SRAM and executes from there. The next time the module is reset it will not startup but will fail.

    "This module had failed earlier and was hard initialized during an outage and did not show the errors, but has NVRAM failure now."

    New INFI 90 "art" has been crafted.  This is the first time we know of that the module status fetch we created has been used to solve a problem.

    FC 222 and 223 Can Have Severe Exception Report Problems

    Summary

    If you have FC 222 and FC 223 blocks, you should check for the following problems:

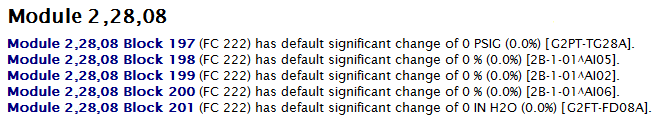
    1. FC 222 S8 defaulted to 0.0 and FC 223 S9 defaulted to 0.0 which causes continuous exception reports if the block is tagged in any HMI.
    2. Spare FC 222 and FC 223 blocks tagged but not used which cause absolutely wasted continous exception reports.
    3. FC 222 and FC 223 blocks with all the significant change specifications set to 1, even when this value is not appropriate.

    Details

    At a client site, DBDOC was responsible for uncovering a significant loading problem involving FC 222 - Analog In/Channel that has been causing significant loading of the node communication capability. It turns out that FC 223 - Analog Out/Channel has the same problem. Here is an outline of the problem:
    • site has significant number of FC 222 S8 and FC 223 S9 blocks at default value of 0 significant change
    • even worse, many of these have "spare" tags identifying unused blocks brought into the HMI by exception report
    • the result is exception reports generated by the node at once per second, many utterly wasted, and the rest far too sensitive to be valid.
    • examination of other systems shows that some have all default values replaced, although there is clearly no understanding that the value is in engineering units (like FC 177) not in percent
    DBDOC tools including the Significant Change Report and the extraction of all specifications made it easy to look for the problems once they were conceptualized.

    In the site in question, a power plant installation, the bulk of the FC 222 blocks were done relatively recently, taking advantage of modern INFI 90 hardware.

    There are 573 FC 222 blocks with default significant change of 0. Our tests with DBDOC Watch Window easily proved that each of these blocks, either if imported or in the HMI tag database, generated an exception report every Tmin seconds, that is, every second. In fact, 92 more FC 222 blocks had non-default significant change, because they had been properly configured.

    What about these 665 FC 222 and FC 223 blocks?
    • One had no tag, but was imported by an AI/L block, so it is generating an exception report anyhow.
    • 196 were named spare blocks, none used in graphics or PI, so196 XR's per second wasted.
    • The other 469 blocks were giving an XR every second.
    The PCU distribution of the load was:
    • PCU 2 - 640
    • PCU 3 - 16
    • PCU 4 - 8
    • PCU 5 - 1
    There actually were 2181 tags defined in PCU 2, which means that every Tmax of 60 seconds, each generated an XR. Thus, the base XR load was:
    • 573 per second from default FC 222 blocks
    • (2181 - 573) / 60 = 27 per second from the other tags
    That is, the base XR load on the node is 600 XRs per second. It is a good thing this system has NIS 21 / NIS 22 communication cards. As it is, this showed that the average communication CPU usage in the node of about 50% was a valid figure.

    Why worry about this?

    554 of the 640 tags and export blocks had default significant change. If the defaulted FC 222 blocks had 1% significant change, the base load would nominally be 2181 / 60 sec or 36 XRs / sec. Allocating 600 XRs per second nominally would allow the analog tags to be increased in sensitivity by a factor of 20, with less load on the system than there is now.

    This investigation also brought our attention to FC 223, the Analog Out/Channel block, which also has a default significant change of 0.

    Guess what? There are 80 of these in PCU 2. They all have the default 0 significant change, so they are generating 1 exception report per second. 31 of them are spare blocks, so that load is doing nothing.
    Bottom line is that, unbeknownst to our client, the exception report loading on the node included:
    • 96 analog in and 31 analog out spares giving 127 utterly wasted XRs per second
    • 469 analog in and 49 analog out tagged blocks giving 518 very, very, precise values every second.
    • 26 XRs per second from the other 1536 "low class" tags, most at default significant change.
    Thus, the load was about 600 XRs per second. If the spare tags were deleted and the defaulted ones set to 1% significant change, the load would be 518 / 60 per second (typically) or 9.

    This node would generate 35 XRs per second as currently tuned. There is lots of XR capability to improve its tags and history data using the capacity that is nearly completely wasted right now.

    How many other nodes with FC 222 and FC 223 blocks have this bad situation?

    The good:
    • Large Australian power plant has 10663. One has default significant change. It is also not tagged.
    • Large Canadian power plant has 1610. None of the 161 that have 0 significant change is tagged.
    • Large American power plant has 1312, none of which is defaulted.
    • Medium size Canadian power plant has 192, all with sig change set to 1.
    The bad:
    • Large Australian process plant has 66 with default values. 16 are tagged, which is a meaningful load.
    The ugly:
    • These small American power plants with all values defaulted at 0 and over one-third tagged but spare.
    • Small American power plant with 88 of 754 with default 0. 86 of these have tags, so they are a load. 21 are spares, so they are a wasted load.
    • Medium size Canadian process plant has 496, all at default 0. 216 are in PCU 171 and 280 in PCU 172. Every one is generating one XR per second.
    • Medium size American process plant has 559 FC 222, of which 368 are tagged with significant change 0. No spare ones are tagged.
    It is clear that the significant change specifications and tags for all FC 222 and FC 223 blocks should be examined. The load can be large, and it can be a waste of a precious resource, even stalling or losing exception reports.

    Postscript

    The general situation with FC 222 and FC 223 blocks that are not defaulted is to have the significant change specification set to 1, no matter what the span.  This is probably an error, too, suggesting that the work was done under the misconception that the specification is a percentage value, rather than an EU one.  1 in a span of 5 is 20%, whereas 1 in a span of 1000 is 0.1%.  Since both appeared in the same system, with the only value used being 1, it is likely the values should be studied even when they are all not defaulted.